Crawl trap: Meaning, examples and limitations
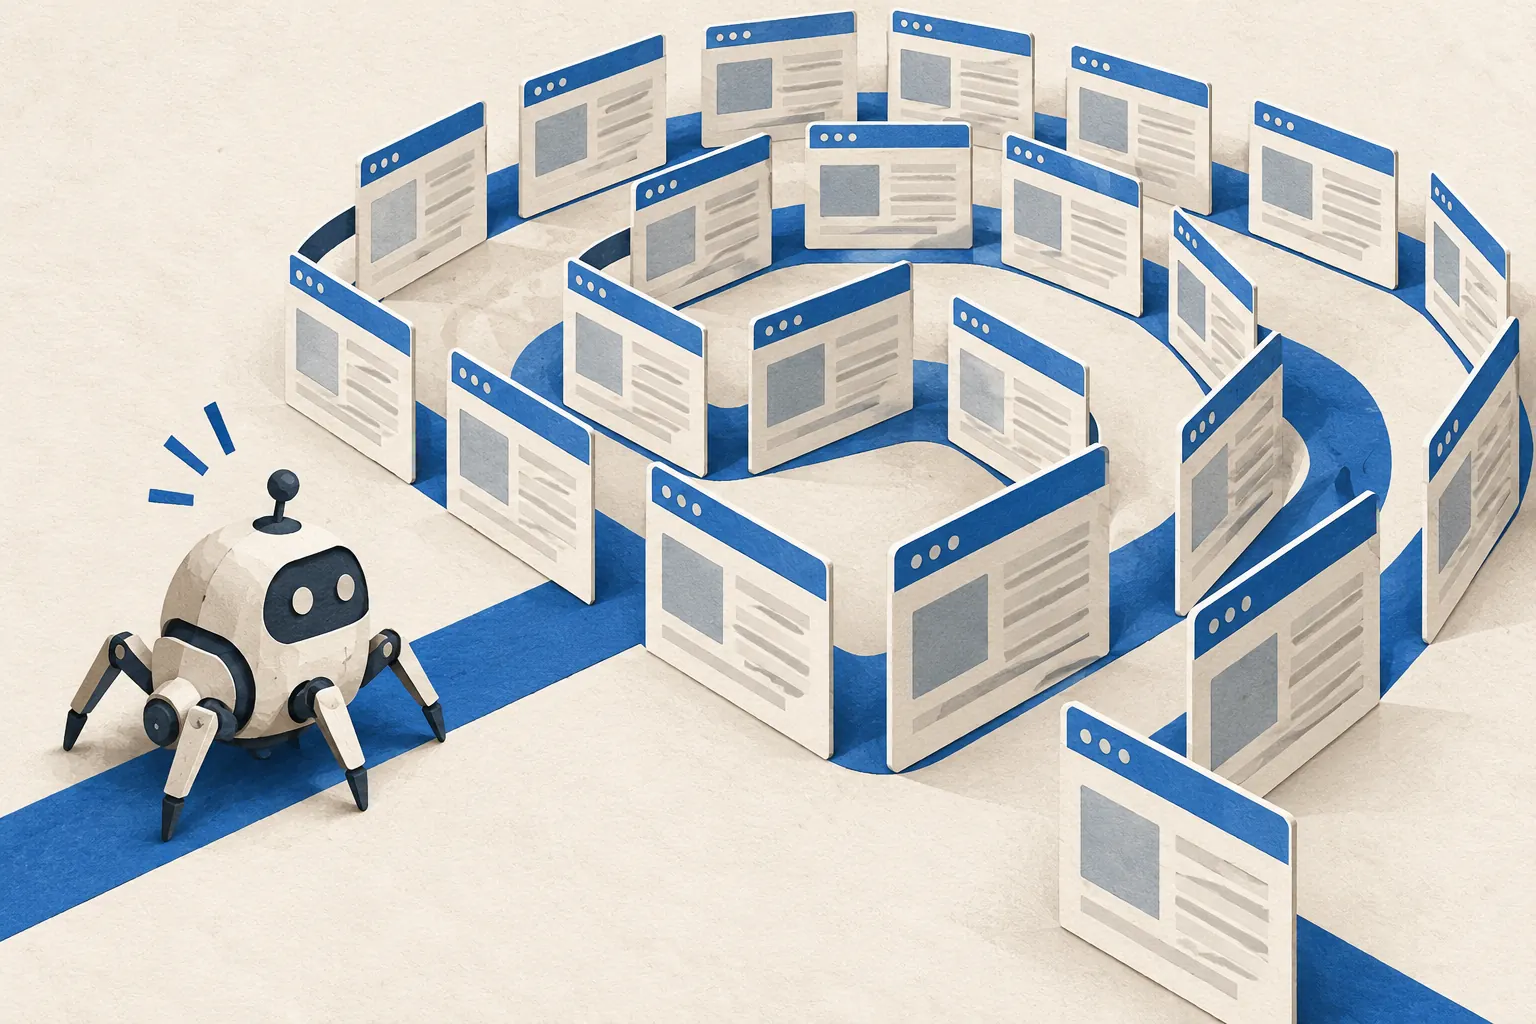
A crawl trap is a website structure that leads crawlers into very large or effectively endless sets of low-value URL variations. Calendars, filters and recursively generated links can create such paths even when the underlying useful content is limited.
At a glance
- The problem is an expanding URL space, not merely a large website.
- Repeated variations can consume crawl and server resources.
- Controls must preserve useful pages and user navigation.
On this page
How does a trap appear?
A calendar may link to the next month without an end. A filter system may combine many parameters in every possible order. If each generated page links to more combinations, a crawler can keep discovering addresses that add little useful content.
Faceted navigation is not inherently wrong. The problem is allowing uncontrolled combinations to behave as an unlimited set of distinct, useful documents. The crawl-budget reference explains why unimportant URL inventories can waste crawling effort.
Example: an empty events calendar
Imagine a business with six upcoming workshops but a calendar that generates pages for every future month. A crawler following “next” can reach years of empty pages. The real information is small; the linked address space is not.
A sensible design bounds navigation to meaningful periods or provides a deliberate treatment of empty states. It does not fabricate workshops to make every generated page look populated.
What evidence identifies the issue?
Inspect request logs, discovered URL patterns and the actual links that create them. Repeated query combinations, ever-increasing dates or nested paths can reveal the mechanism. A high request count alone is insufficient: a large legitimate catalog also creates many requests.
Trace a few examples from the entry page through the generated links. This shows whether the next variation adds distinct value or merely repeats the same result.
How are traps controlled?
Review link generation, parameters, canonical choices and crawling rules together. A robots.txt rule may limit fetching, but it does not repair the site's navigation or guarantee removal of already known addresses. Avoid blocking useful categories indiscriminately. The goal is a finite, intentional public inventory whose links and responses reflect actual content.