Googlebot: Meaning, examples and limitations
Googlebot is the common name for Google Search crawlers that retrieve web resources for processing. A Googlebot visit establishes that a request was made; it does not by itself prove indexing, a ranking position or inclusion in an AI answer.
At a glance
- Crawling, indexing and ranking are separate stages.
- A user-agent name alone does not prove that a request came from Google.
- Different Google crawlers and fetchers have different purposes.
On this page
What happens during a visit?
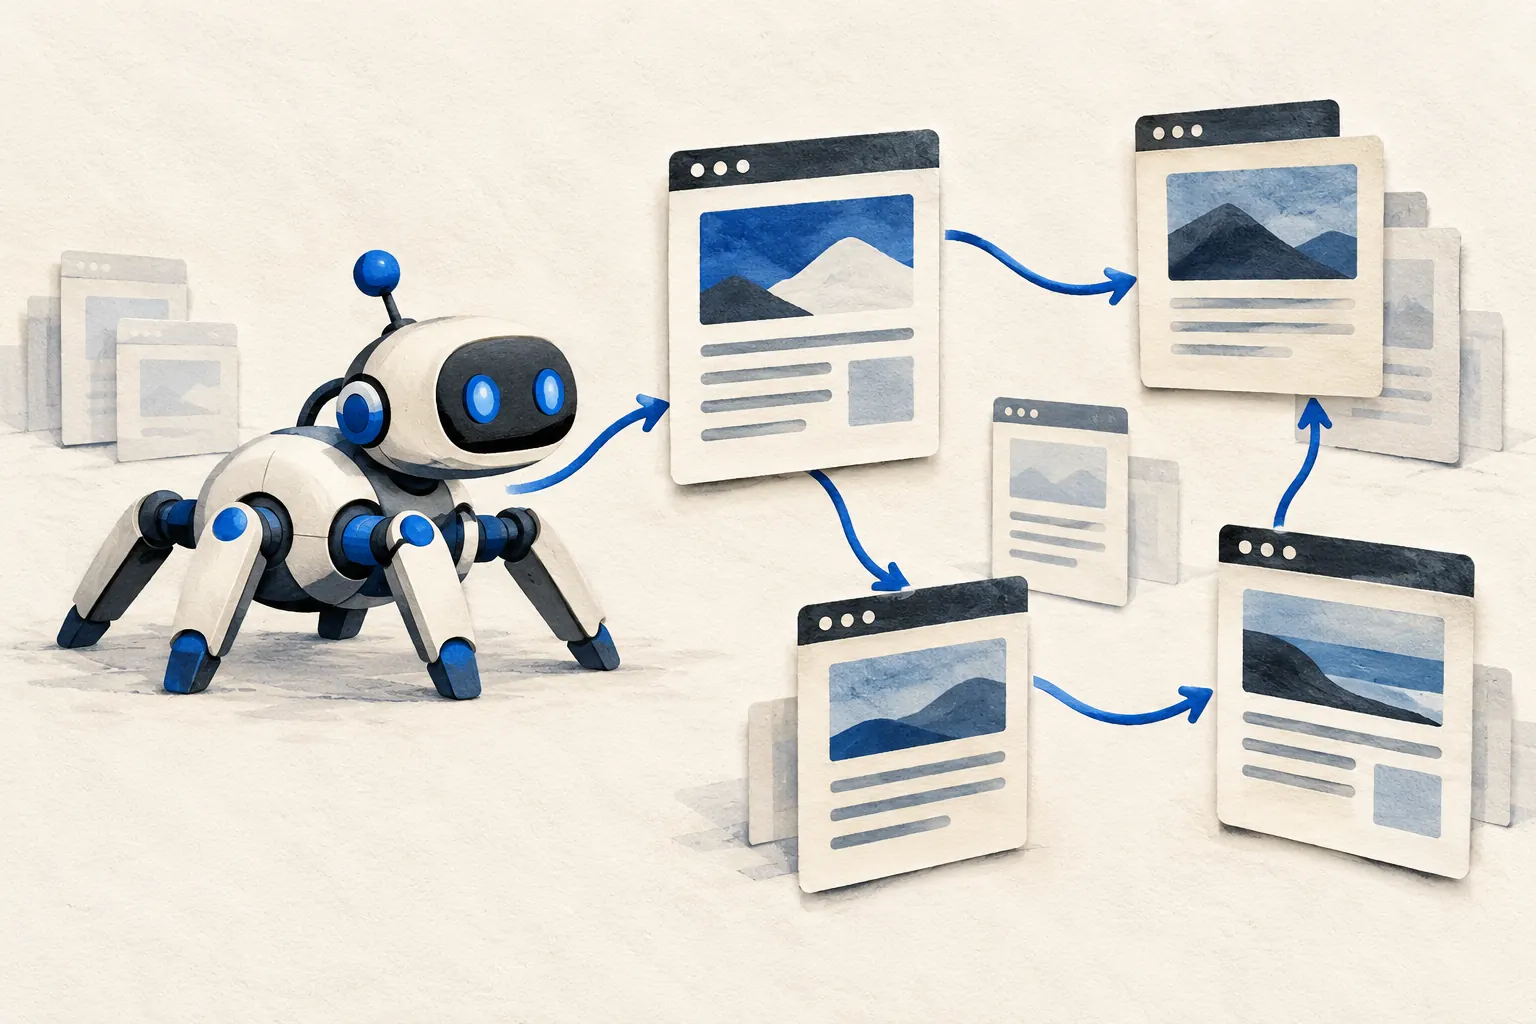
A crawler requests a URL and receives a response with a status, headers and possibly content. That exchange is part of crawling. The returned material may then be processed, but the request itself does not establish that the page was selected for the search index.
Resources such as images, CSS and JavaScript can matter to processing too. Looking only at HTML requests may miss a blocked dependency that changes the rendered page.
Example: a crawler in the server log
Suppose a shop's logs show a request labelled Googlebot for a new buying guide. First verify the requester and the returned status. A 200 response and readable article are more informative than a bare request count, but still do not prove a search appearance.
Use URL inspection to examine search processing evidence separately. A crawl log and a search-performance report answer different questions; neither should be substituted for the other.
Is every Google request the same crawler?
No. Google documents common crawlers, special-case crawlers and user-triggered fetchers. Their purposes and access behavior can differ. The official verification reference identifies the relevant categories and methods.
Do not assume that a user-triggered inspection or another Google service is identical to a routine Search crawl. Similarly, allowing Googlebot does not automatically allow every AI crawler.
How should a claimed visit be checked?
The user-agent string is a self-reported label. Verify the source using the provider's documented method rather than trusting the name alone. Then inspect which public URLs are reachable and whether useful content is present. Successful access is an input to search processing, not a guarantee that Google will recommend the business.